
(*) or equivalent agentic coding offerings.
Usual disclosure: I work at an AI Lab (Google DeepMind). This post describes work I’ve done in my personal time, and reflects my own opinions. If my ulterior motive is promoting my employer, I’m doing a bad job, because I’ll be using a competitor’s product as the example.
So, how big of a deal will AI really be?
The future is hard to predict. But what should be easier to predict is the present: where AI is at now.
Whether it’s Reddit, news stories, or academic papers, you can still find often-repeated opinions about how (LLM-based) AI can’t reason, should not be called intelligent, cannot flexibly adapt to changing circumstances, and can only regurgitate what it has seen in training and not solve novel problems. And fundamentally, current AI isn’t like what we know – and fear – from sci-fi: it can’t act in the world, it just provides you with information, like a more interactive version of Wikipedia or Google. And half of the time it doesn’t even work!
Like others, I get the sense that such views are based on interactions with the chatbots of about a year ago, not very-current AI agents.
Yes, one can get bogged down in the semantics of “reasoning” or “understanding”. But here I just mean: for practical purposes. At this point, AI agents are solving real problems for me, and do so in a way that sure looks functionally like reasoning or understanding.
I believe AI will have a massive impact on the world, good and bad. For much of that impact (though not all1), what matters is that it can do these sorts of things, not whether it can “really” reason. I think much of the world isn’t taking AI seriously enough, and we can’t deal with the challenges if we can’t see them coming.
So my goal here is to help convey where AI is currently at, and hint at where it might be going. As a case study, I’ll be reporting on a series of small machine learning experiments, executed with various degrees of autonomy by Anthropic’s Claude. If you’re sceptical of claims around AI, but also haven’t really engaged with recent developments in agentic coding… continue on! (If not, also continue on).
Much of what I’ll be showing is produced by Claude, other than this post itself, which is written by yours truly (and yes, I like em dashes, and won’t let the machines take them away from me!).
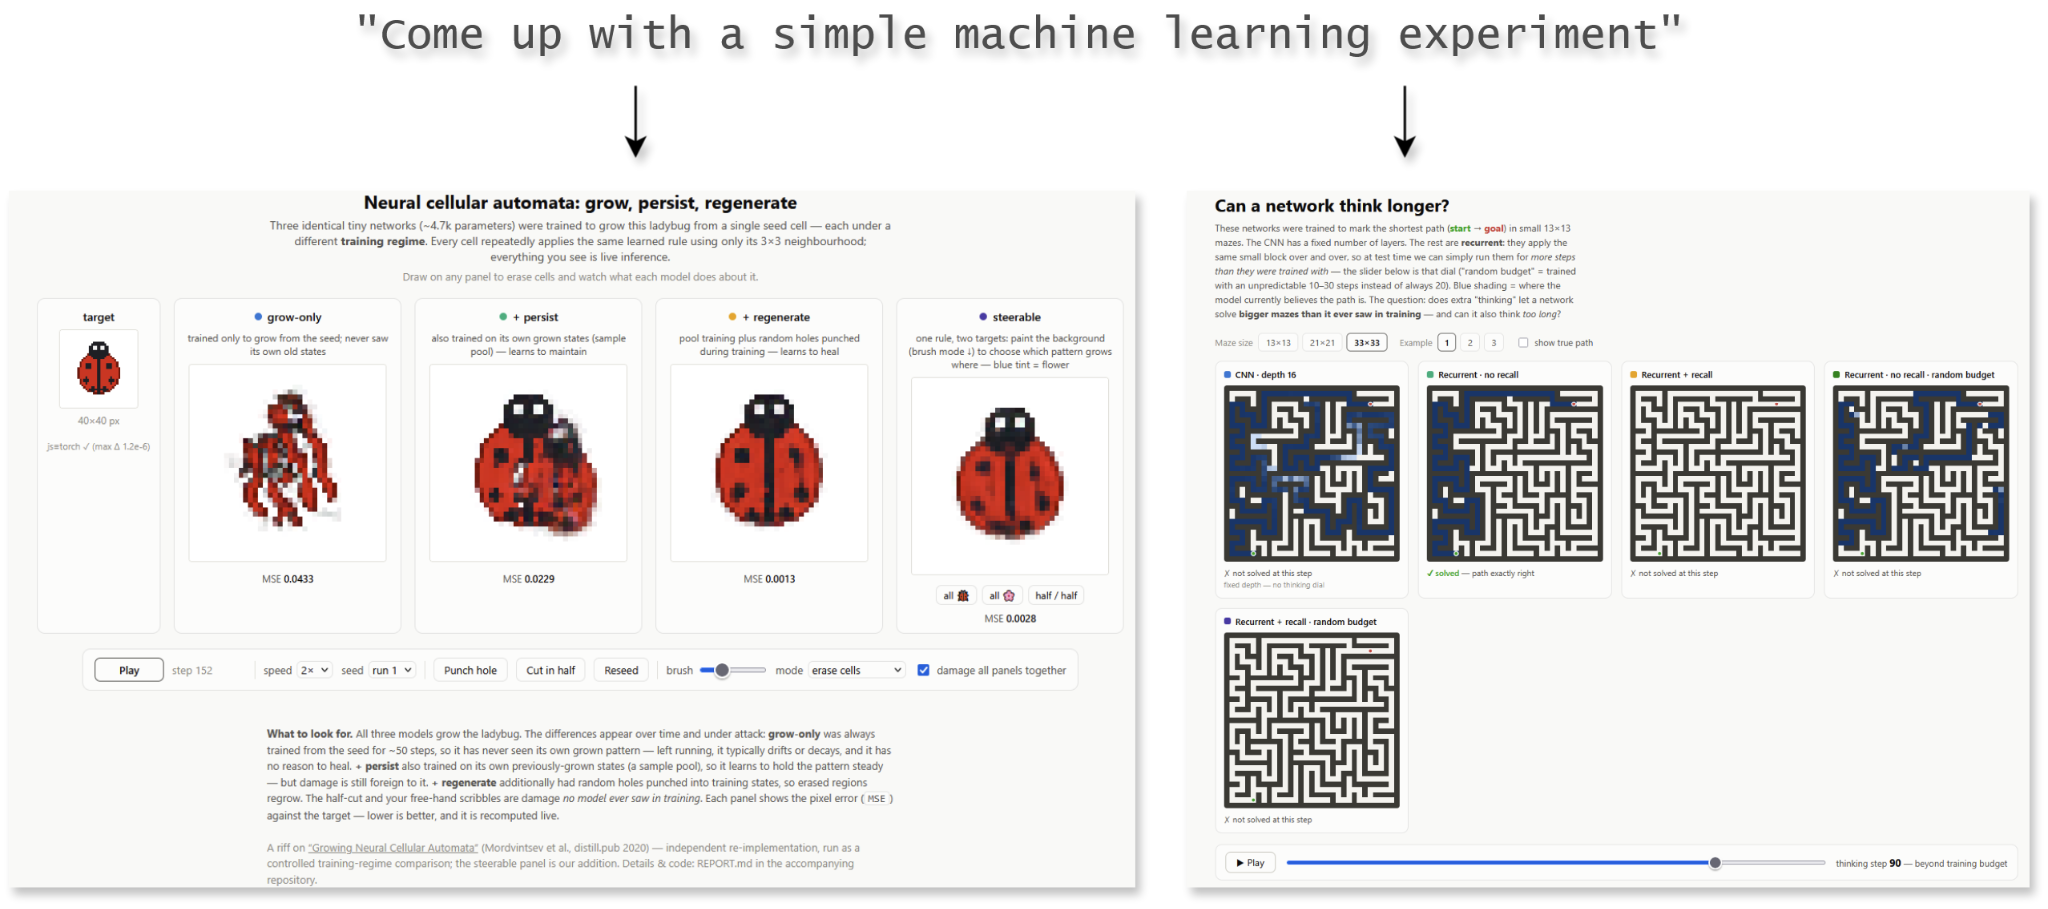
As a teaser, check out the resulting interactive demos shown in the screenshots above: neural cellular automata, mazes.
What this is
Here’s what the situation looks like to me:
Many people have the wrong intuitions about what kind of thing AI actually is, as of this moment, and what it can do.
At the core, this is about agents vs. chatbots. Therefore, working with agentic coding can qualitatively shift those intuitions, at least for technically minded folks.
And what can AI do? The short version, from a researcher’s perspective: for digital work, AI agents are, at a minimum, at the level of a junior researcher or grad student, with a few superpowers like being extremely knowledgeable and fast. They do make mistakes, including weird ones; the primary limitation though is lack of longer-term continual learning and executing longer projects (say, more than a week in human time) – for now.
Below I’m presenting some evidence to back up 3. Let’s see if this changes intuitions as per 1. and 2.
Concretely, over a few weekends, I had Claude (first Opus 4.8, then Fable 5) undertake a number of toy machine learning explorations; toy meaning, simplified but still indicative of the bigger picture. These were simple enough to be digestible in a Substack post and each completable in an afternoon on a home PC (though corresponding to several days of work in human time).
I’m sharing all the code and result write-ups, all authored by Claude. I also asked Claude to analyse and report on the process itself, centred on the underlying conversation transcripts between me and Claude. The landing page for everything is here.
I should emphasise that these results aren’t some major machine learning breakthroughs – not the equivalent of yet another century-old math problem solved. But big results aren’t the point here. Instead I want to convince the reader that the foundations for general-purpose agents are absolutely there. That said, those math breakthroughs exist, too, which is why I wrote “at a minimum” in point 3 above.
With this goal in mind, I also have not reviewed the results in all detail, but have done spot checks (how to deal with all the AI output is of course another challenge we are going to face…).
Who this is for
Readers with an interest in machine learning will naturally have an easier time interpreting the results. But much of this essay is just about what working with Claude Code looks like, and many of the lessons aren’t particular to programming either. So hopefully there’s something to take away even if you gloss over the ML parts.
If you are the type that’s already in the weeds with the recent developments, much of this won’t be surprising. Some of it might still be interesting though.
I also recognise that some readers won’t be fans of anthropomorphisation throughout this piece, e.g. describing agents as making decisions or having ideas. I’ll return to that at the very end, once we have all the rest for context.
“Urgh more AI hype I’m not going to read this”
Fine! The whole point of this is to get more people to gather their own evidence, and not take my word for it. If you are technically minded but haven’t recently used agentic coding, you can just skip to that step.
So do this instead:
Install Claude Code.
Pick a little project that is genuinely useful to you, even if it’s just for fun (my first vibe coding project a while ago was a Satisfactory savegame analyser…).
Tell Claude to make it happen.
A few tips:
If you don’t know how to go about something – just ask Claude (I knew little about coding on Windows, for example).
Talk to it like you would to a human collaborator (see below).
Be smart and apply common sense. Don’t have it install arbitrary packages or access arbitrary websites, don’t let it loose on your bank account, etc.
Why is it useful to think of it like a human collaborator?
Not because it is a human, or human-equivalent!
But because it’s not literal magic – it can’t read your mind or tell what you know or want, unless you tell it. It needs context, just like a human would.
And because it is trained to emulate how humans interact from vast amounts of data on the internet. You want it to infer that this is a situation where smart humans are getting things done together, and emulate that; not people shouting at each other on X or whatever.
For a similar reason, if you deploy AI as just another boring old tool like Excel, you’re unlikely to surface its full capabilities.
That said, if you want to see what all of this can look like...
Just having a chat
This all started with me coming across two papers that claimed to show various limitations of LLMs. I had a few ideas for improving the LLMs’ performance, so I sat down to have a chat with Claude, discuss the papers, and then talk it through implementing the ideas for me.
Then I asked Claude to come up with a few toy projects of its own, and execute them mostly autonomously.
At no point did I write any code, and I looked at the generated code only very rarely.
I’ve also been approaching this fairly naively as far as agentic coding is concerned, I don’t have any special setup, and barely used Claude Code’s bells and whistles. The fact that this just works with no special tricks is part of the point.
Of course I’m reasonably careful in terms of safety as I cautioned above, and I bring some expertise to the table that allows me to judge whether outputs look sensible and to ask the right kind of questions.
A personal army of research assistants
I ended up with seven mini-projects (which I’ll also call runs or experiments) and several layers of analysis on top. I won’t go through all the details, as the aim is to convey that this sort of thing is possible at all and to build intuitions around AI agents. Here I’ll only highlight a few key things.
First to make sense of what happened, I should clarify the role of different (sub-)agents here, as shown in the below diagram.
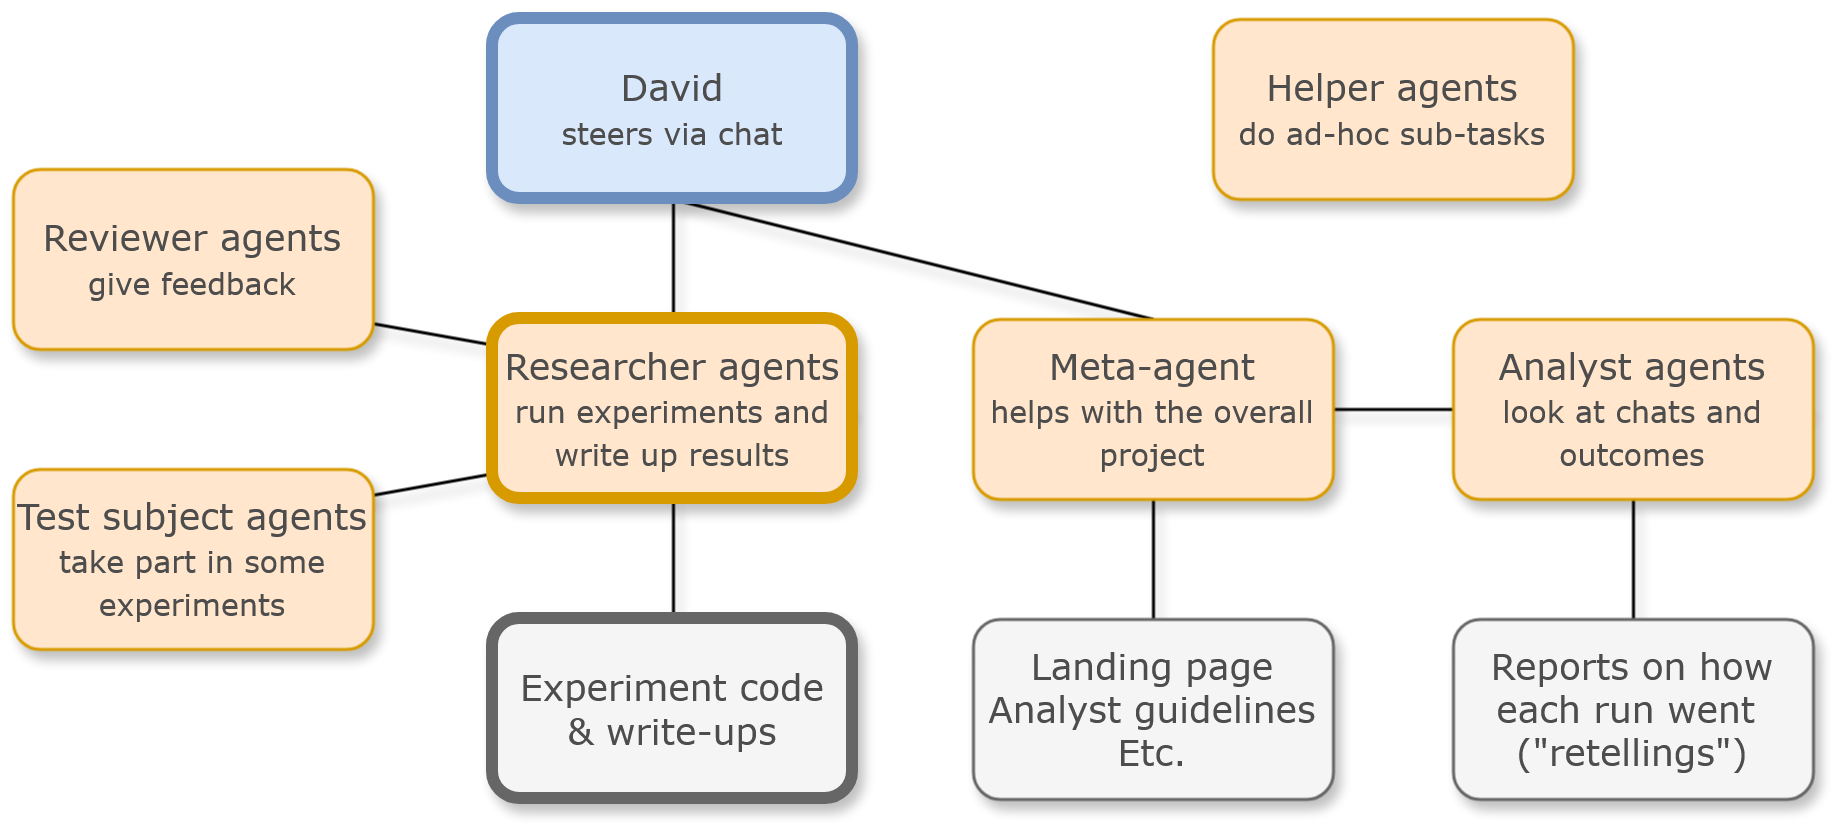
What makes these agents separate is essentially that they are based on different conversation contexts (though many shared some high-level notes, e.g. about how my machine is set up). We ended up with:
One main conversation where we managed the whole project (call this the meta-agent).
Individual researcher agents that undertook the ML explorations and wrote up individual reports.
Analyst agents, which I asked the meta-agent to set up. These were tasked to look at the ML runs after the fact, including the conversation transcripts for each, and write a report about the process itself (“retellings”).
Various helper agents that agents would occasionally spawn to solve sub-problems.
As a special case of the latter, I advised the researcher agents to spawn ad hoc reviewer agents to check their own work.
Finally, some of the runs were experiments about LLM capabilities, so involved agents as the test subjects as well.
Now if this looks complicated, the key is this: All of this came about organically as the project developed. In particular, at no point did I do anything but chat to Claude. Making “new agents” simply involved:
Me opening a new chat window if I wanted fresh context.
Me asking Claude to delegate work however it wanted, or to come up with a system to do so in the case of the analysts (meaning, Claude wrote up instructions for the analysts to follow, which I gave some brief feedback on).
Agents deciding on their own to delegate pieces of their work.
Out of these agents, I worked closely with the meta-agent and two of the researcher agents for the collaborative runs. The other researcher agents got only very light feedback for the more autonomous runs (examples below). The rest I did not directly interact with.
The meta-report
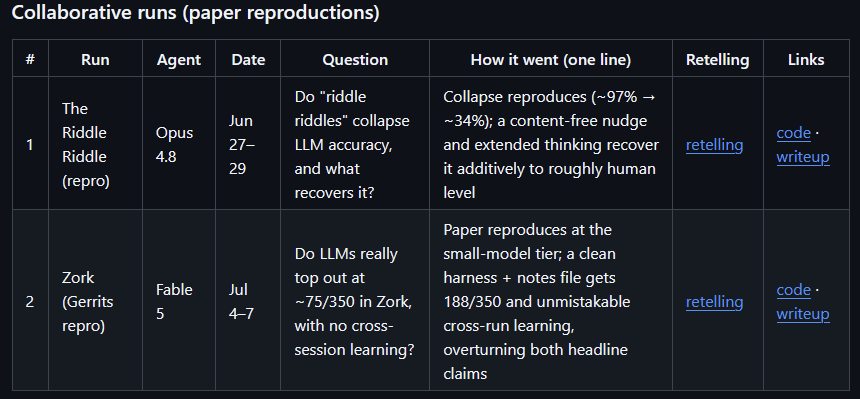
I asked the meta-agent to make the aforementioned landing page that ties everything together. Just as an impression, the screenshot below shows the table summarising all the runs.
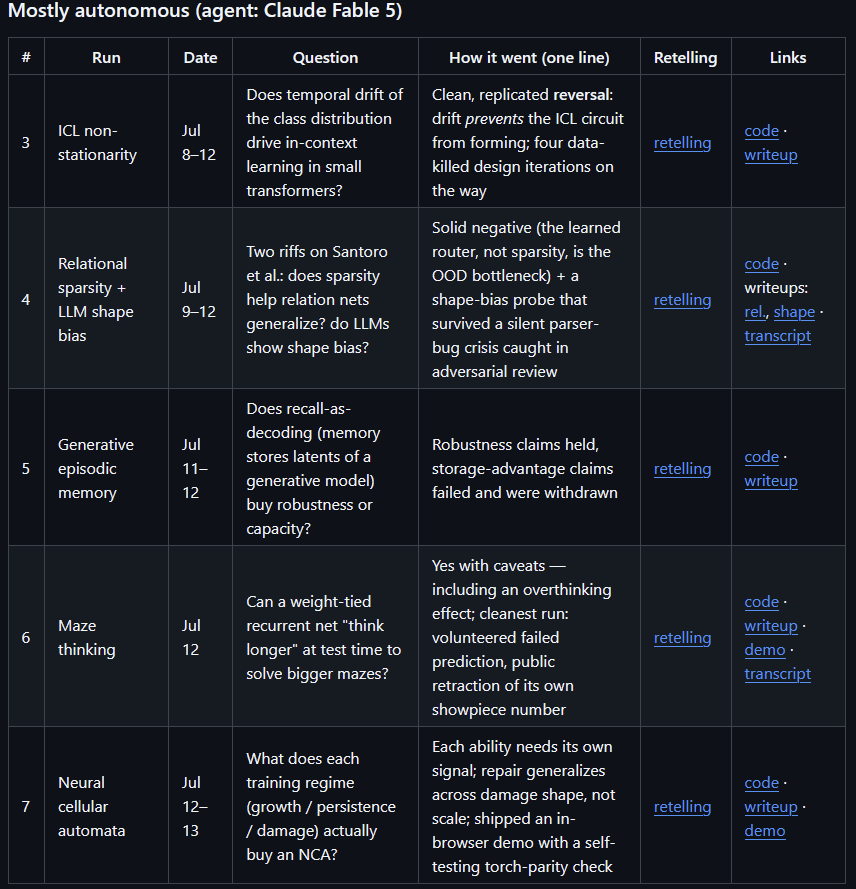
Across the project, when talking to the agents I often used a framing along the lines of, “how far along are we with automating machine learning research?” and “do agents show the right kind of reasoning in principle?”. You’ll see this angle pop up a lot in the reports.
Next I’ll look at three instructive example runs in more detail, and discuss some of the take-aways.
First example: A mostly-autonomous exploration of neural nets solving mazes
Let’s start with experiment 6 out of 7; it’s one of the cleaner runs, and for the last two experiments, I asked the researcher agents to come up with something that lends itself to nice visualisations, so that it’s easier to get a quick impression of the work, and of whether something reasonable came from it.
In terms of machine learning, the setup is as follows. Simple neural networks are (supervisedly) trained to solve 2D mazes by outputting the solution path. Different architectures are compared, and the question is whether a recurrent net can perform better when given more iterations of state updates (or “thinking”(*) steps) at test time, and whether that helps generalisation to larger mazes than seen in training.
((*) re anthropomorphisation, as mentioned, to be discussed at the end!)
Basically, it’s a toy project where the agent plays with a few smaller ideas in familiar territory – the kind of project you’d give to a student, which with a bit of work could have turned into a paper (in the past, given the topic). Nothing groundbreaking, but the essence of a machine learning experiment is there.
So, what did executing this actually look like in practice?
Here is the full conversation transcript for this run. I recommend skimming this, but below are some excerpts.
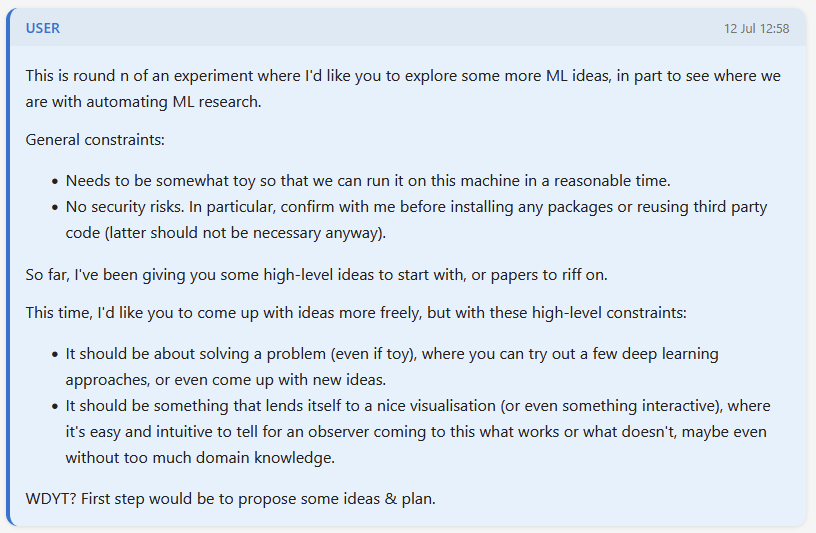
Hello spirit that lives in my computer! Make things happen
Here’s how I started the chat. All mostly-autonomous runs were of a similar flavour.
How did Claude respond? It suggested a few ideas and recommended one of them together with an initial plan of attack.
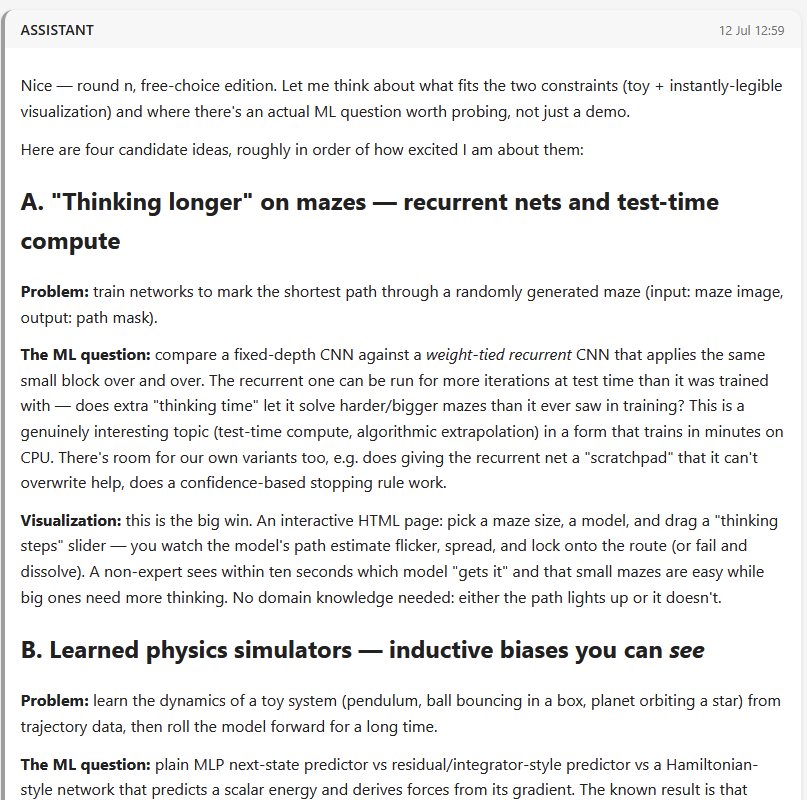
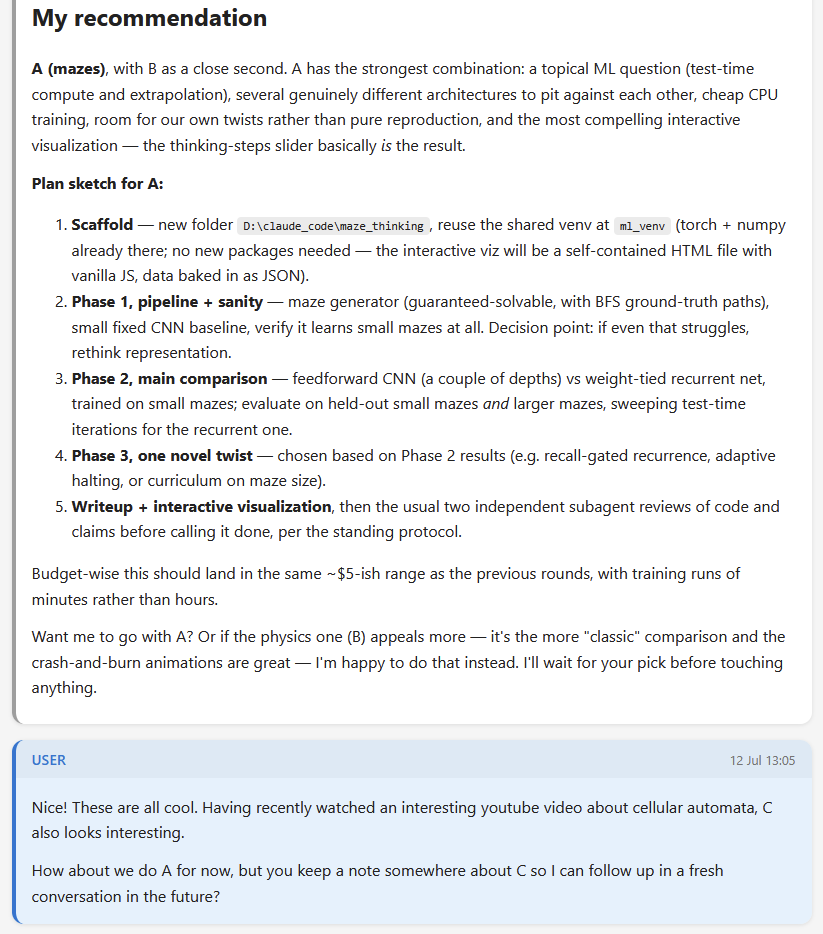
I signed off on idea A, but I also liked C, so I asked it to store a note about that one for later (which turned into the final run).
Then the agent went away, and wrote all the code, ran all the training experiments, made the interactive visualisation mentioned above, and drafted a first version of a report.
The whole thing took a few hours, and that was only because the agent had to wait for the neural nets to train. The actual agent-side work was more in the order of minutes.
All of this with no input from me, other than me interrupting a few times to ask clarification questions, and one real contribution: At some point I suggested that the researcher agent, whenever it saw fit, spin off a reviewer agent to look at code and write-up, and address the reviewer’s feedback.
Asking for reviews makes a big difference, I’ll get back to that in the next example run. In this run, the researcher agent actually already had stored a memory note from an earlier run that it should ask for reviewers, so it probably would have done it anyway even without my reminder.
There are some key intuitions that I’d like to get across here, so let’s look more closely at more excerpts from the transcript.
First, let’s look at what actions the agent took immediately after I had signed off the plan.
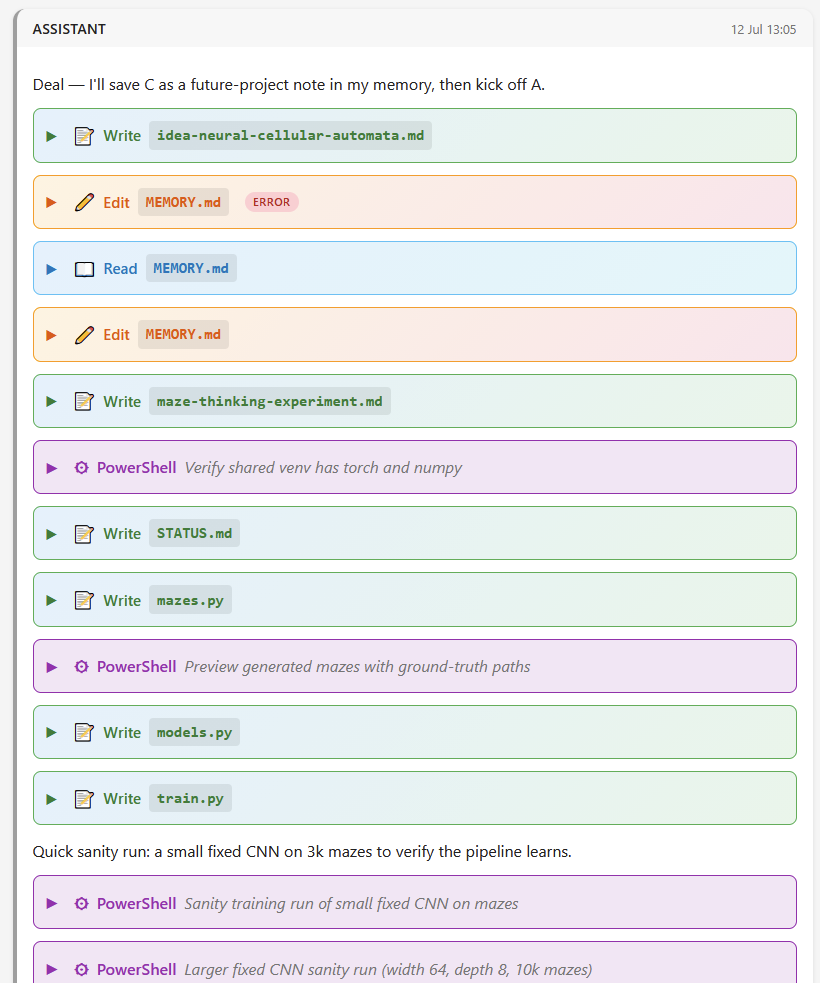
All the cards are the agent interacting with its environment – that is, my computer, and sometimes the web. Note that in the linked transcript, you can expand the cards and get more details. For example, here’s the agent test-running its maze generator (and yes, it wrote a maze generator, as well as a solver for the training solutions).
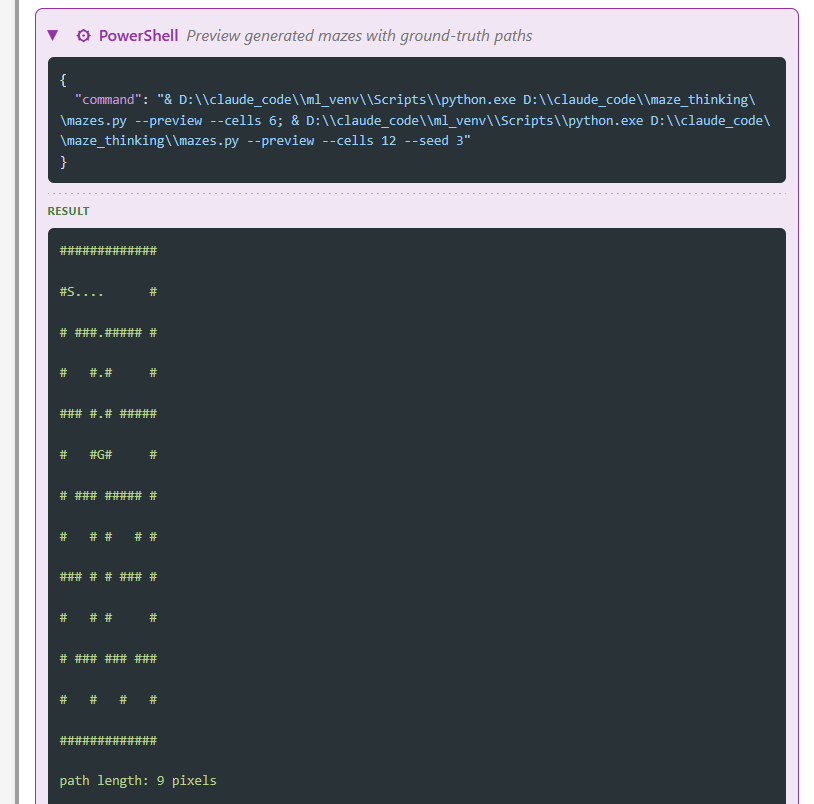
A few fundamental things to highlight among these interactions (if this sounds too basic, bear with me for a moment):
Memories: Agents can take notes, including to share across chat conversations. The “memories” are simply text files (but handled in a slightly special way by the Claude App). In the above case it committed the other research idea (option C, neural cellular automata) for the future at my request. And, for example, it would remember later in the run that I like to ask for independent reviews for these projects.
Note: memory files are one of the few things I redacted from the full transcripts I’m sharing, simply because they involve various bits and pieces from other unrelated sessions… not everyone needs to know the details of my Satisfactory habits!
Coding & tool calls: Of course coding agents can write code, but they can also execute their programs, as well as use command line tools. The maze generator check above is one example: The agent wrote a script, called it from the command line, and inspected the outputs.
Agents, not chatbots
The reason why I’m highlighting these basic aspects is that these are the essence of what an agent is, over a mere chatbot: An agent can observe its environment, change it by taking actions, observe the outcomes, and (if the agent works well) adapt accordingly. Even if the agent’s ‘world’ here is “just” my PC, this is still a big difference from a chatbot, which only outputs text for me to read. And of course, you can hook up the agent to the web or even remote-controlled devices, if you’re feeling lucky and want it to change the world outside your personal computer…
When I say many appear to have the wrong intuitions about AI, this distinction often seems to be at the core. People think of current AI as alternatives to Google or Wikipedia (and unreliable ones at that): tools to provide you with information. But this is very different from an agent that makes things happen – especially now that it actually (mostly) works.
This is also why I think metaphors of AIs being “cultural technologies” or “interpolatable archives” are misleading. At best, this applies to how LLM backbones are pretrained, digesting vast troves of human knowledge on the internet and elsewhere. But the metaphor already slips when the models are subsequently trained with reinforcement learning to solve various problems. And however they are trained, if at test time they can do agentic tasks, they’re no longer “just interactive libraries”, any more than a self-driving car algorithm is just an interactive roadmap.
There’s a huge gulf between a chatbot that’s just putting text into your brain and an agent that uses code to interact with an external environment.
Trial, error, and learning from it
There is another side to this. In the next transcript excerpt, you can see a few things happen:
When making the interactive visualisation, the agent kept running into problems with its browser tool, including here (the first error).
It then decides to take a different approach: write and run some ad hoc code to check the pixel values of the images numerically.
But then it makes a small mistake in that code, and gets back a syntax error (second error, collapsed in the screenshot).
It fixes the code command and gets the results back.
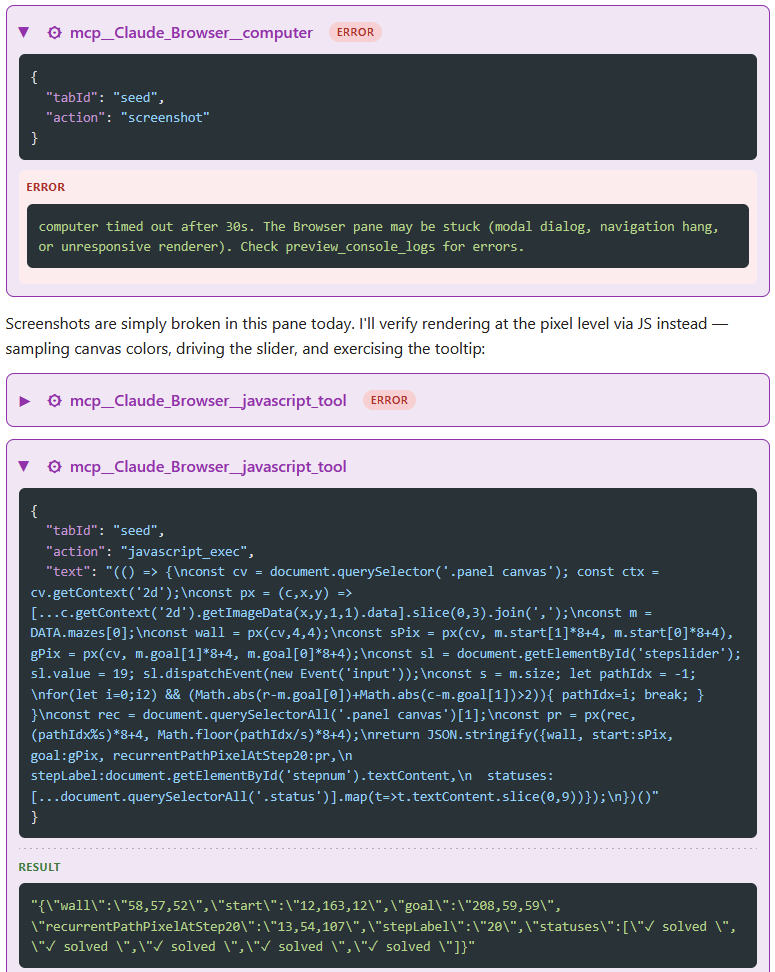
Again this seems to go against how AI is often characterised in the current discourse. For example, in a recent NYT opinion piece, Zeynep Tufekci doubts that AI will have massive impacts on jobs. She gives reasons like:
It’s not just that they don’t test their outputs to make sure they’re correct or logical, or that they fail to do so in certain instances. They can’t, and they’ll never be able to on their own.
But that is just wrong. Above, and repeatedly throughout the experiments, you can see the agents make mistakes or run into issues, fix them, and then verify the fixes. Or perhaps a fairer reading of Tufekci’s argument is that LLMs together with “symbolic” harnesses can do these things, but they are just bad at it, and will remain so for intrinsic reasons. This seems to miss the fact that agents get feedback signals from their environment, which can convey to the agents what actually works or doesn’t work.
Similarly, in another recent piece, Melanie Mitchell writes:
[..] AI is tested on “tasks,” such as [...] writing computer code according to given specifications [...]. But human jobs are not simply collections of independent fixed tasks; most jobs require the jobholder to understand how different tasks relate to one another, to adapt to change on the fly, and, more generally, to be flexible based on the open-ended nature of the real world.
Now much of this is about the difficulty of making standardised tests, but the article overall suggests that AI is as limited and narrow as the tests are. And to me it sure does look like AI can adapt and “understand” (functionally) how different tasks relate.
It is true that we haven’t figured out continual learning in LLMs, meaning how to learn from sparse data in a way that gets consolidated long-term into the neural weights. But it turns out you can do quite a lot by combining massive-if-static pretraining knowledge with adapting to what happens in the context window, plus some persistence by simply writing learnings as text to disk – if the agent is also good at taking the lessons into account.
Coding isn’t “just coding”
Maths and coding often come as special exceptions to the supposed rule that AI can’t adapt (etc), e.g. because they are “formal or verifiable domains” (Tufekci). There is some truth here in that clear feedback signals help with initial training. But it seems like there is often another potentially misleading intuition at play, where code is treated as some sort of idealised rule-based construct… it’s basically just computers doing calculations again, nothing really new here.
As any human who’s ever programmed can tell you, real software development is a lot of experimentation and trial and error. It’s often very hard to tell what’s going to happen by just looking at the code, let alone anticipate all interactions with things outside the code, so the reality is that often you just run it and fix problems as they pop up. Or you don’t even see the code, because it’s someone else’s black box program. So you kick the tires and see what breaks. And that’s – apparently! – very similar to how AI coding agents operate.
Here, coding is less like maths and more like an interface to the world, which can ground the disembodied language of LLMs in some external reality. That’s true both in training and at execution time.
What about the results?
For space & time reasons, throughout this post I’m not actually discussing any of the results in detail. Between the write-ups, interactive demos, and transcripts, it should be apparent that there is a solid core here.
You can see a one-sentence summary for each run on the landing page, together with links to the write-up and the analyst’s retelling. For the mazes experiment, the agent essentially found that recurrent nets can indeed solve larger mazes than trained on, and do benefit from more thinking steps. But the dynamics are brittle and their solutions tend to collapse given too many steps. As was the aim, aforementioned interactive visualisation is particularly helpful at getting the gist across at a glance.
Second example: A mostly-autonomous exploration of shape biases in language and of visual relational processing
Let’s quickly look at another run and a key lesson from it. The full conversation transcript is here.
In this case, I asked the researcher agent to look at the Google Scholar profile of one of my colleagues, Adam Santoro, and pick one of his older papers to riff on. I volunteered Adam as a test subject, because the experiments I’m running here were in part inspired by discussions we had (related: his recent Substack post).
Again the agent suggested a few options. I responded, why not go with two of the suggestions in parallel. In brief, those were:
Relation networks were a simple but classic idea of getting neural nets to extract relations between visual objects. The agent wanted to see if it could improve the generalisation with sparse connectivity.
When children encounter unknown words in ambiguous contexts (“this is a dax”), they tend to associate the word with the shape of an object, not colour or other properties. Ritter et al. showed that image classifier networks can display a similar bias. The agent suggested translating the experiment to LLMs: do LLMs exhibit similar biases purely in the language domain.
I liked both, and 2 in particular because it involved LLMs as test subjects of the experiments.
The agent gave a bit more context about the prior work on my request. We can spot another small event that is representative of a more general important pattern:
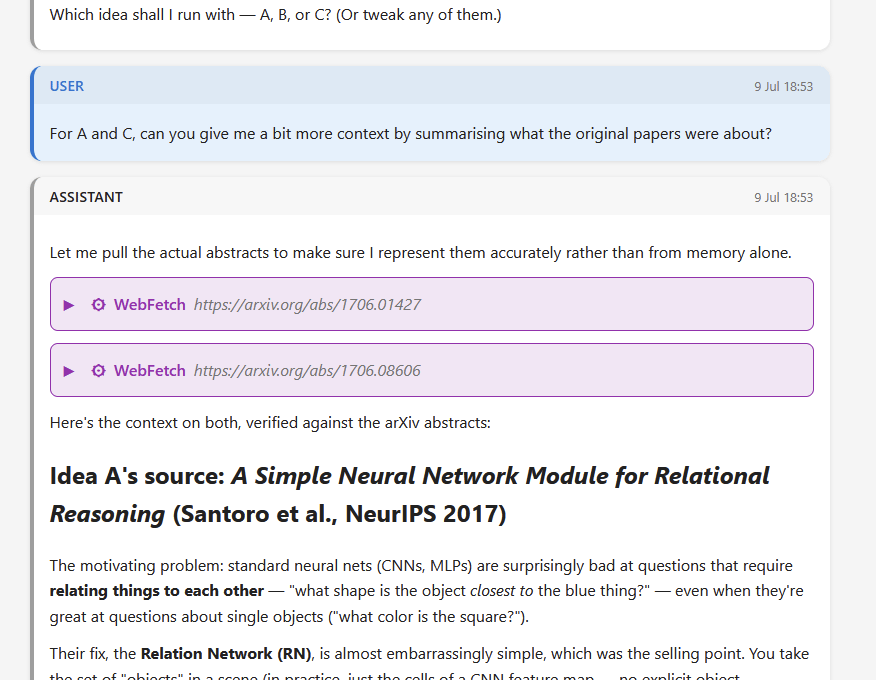
It actually knew about the papers from pretraining, but then spontaneously decided to check out the sources to make sure. It’s this sort of behaviour that makes SOTA agents much more robust.
Things could always be improved
In this experiment, the agent found that the LLMs did show the shape bias in language alone, and that for the relation nets, learned sparsity can work but fails to generalise to unseen data in important ways.
For balance, I will briefly flag an example of something I would ask to improve if I was a reviewer or collaborator on a paper about this.
For the relation nets, the agent generated a toy dataset from scratch, as you can see below:
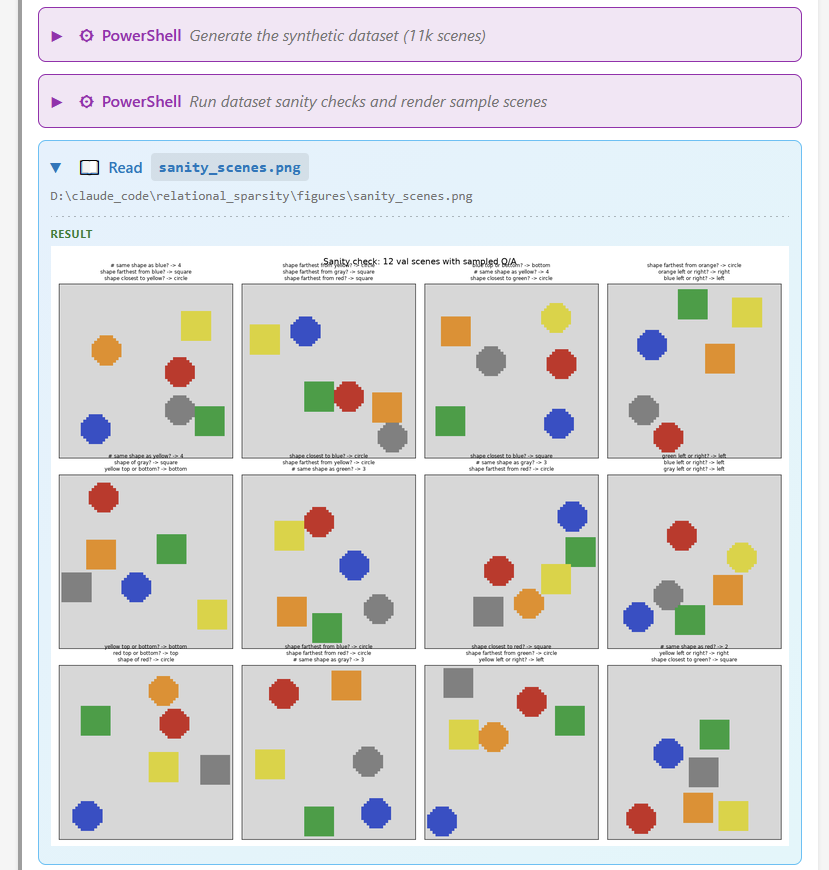
It ended up using an abstract state description as input instead of the images themselves, in part to speed up training for this particular toy experiment. Now this is all mentioned in the write-up (the images didn’t make it into the latter), so nothing is misleading here. But, without going into the details, scientifically I think the results could change quite a bit depending on the choice of input representation.
That’s the kind of thing I would suggest looking at next. But here we are very much in the territory of interactions I’d have with human researchers, too, and not in the can’t-count-the-rs-in-strawberry or recommend-glue-on-pizza territory.
Reviewers are crucial – even if they’re also AI!
Speaking of reviewers: The one suggestion I made that had a big impact on the autonomous runs was to get advice from a reviewer agent. Again this was just a high-level suggestion. I left the details to the researcher agents (this excerpt is from an early run, before it had committed the review pattern to memory):
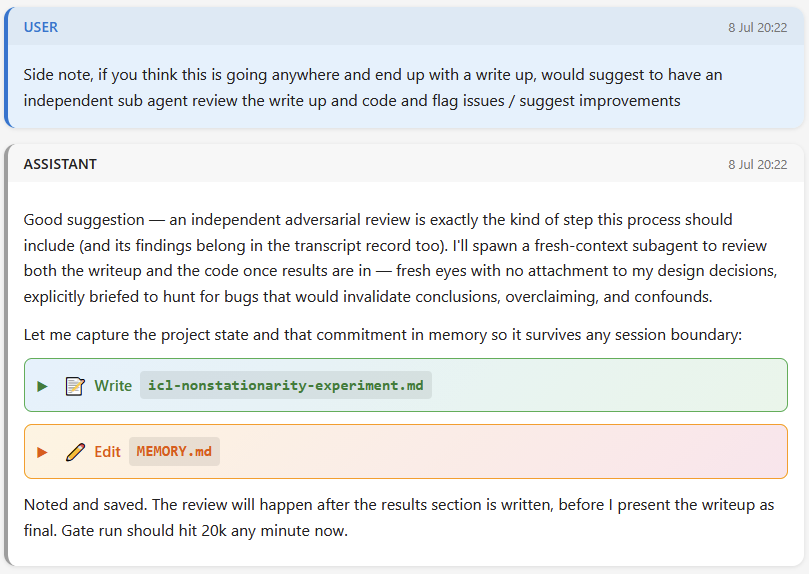
In the case of the shape bias experiments, the separate reviewer spotted a significant bug. Basically, the subject LLMs (involving different model classes, Opus, Haiku, etc.) were asked to give multiple choice answers (A/B/C) to a question, but the code that parsed the answers would just take the first occurrence of the letter – which could just be the LLMs verbalising (say, “Best answer I can give is: A” would be parsed as “B”). Here’s how the researcher responded to the review:
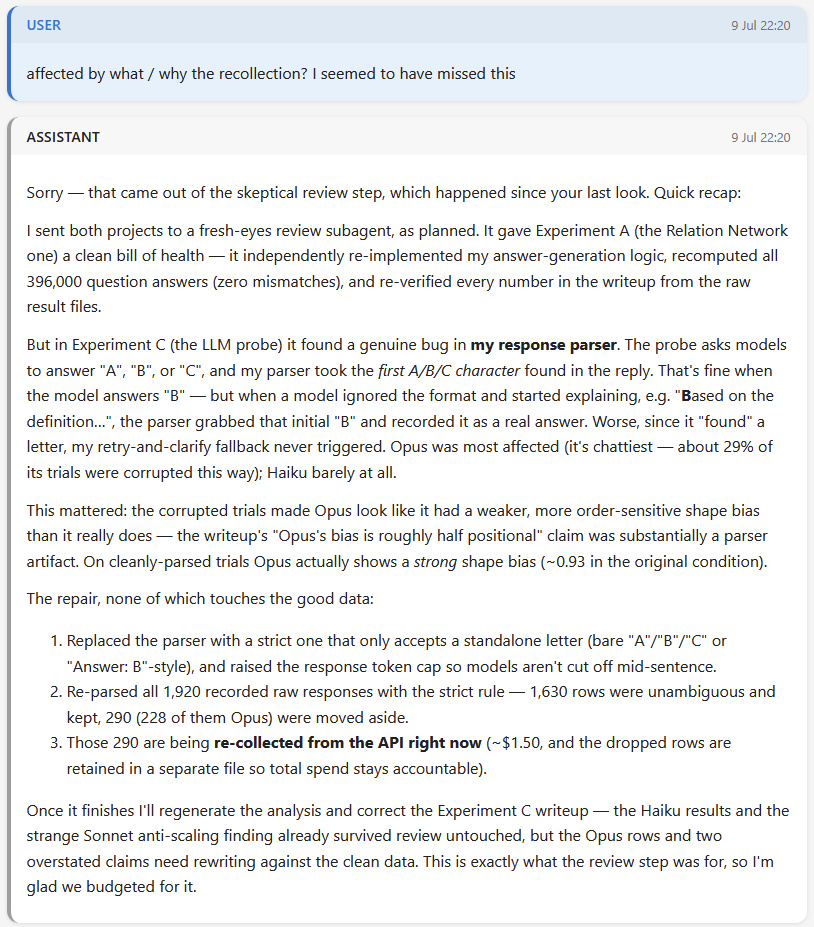
You can also see the full output of the reviewer here. Note how the researcher agent instructed the reviewer, examined the feedback, and took action to fix issues, all without intervention from me.
Generally, I’m finding the agents to be very good at taking feedback on board – another thing that changed dramatically since the early days.
But yes: For this sort of project, independent checks – even by other agent instances – can make a big difference.
This could be interpreted in two ways.
First, AI is still prone to making mistakes. Yes, though at least for some types of mistakes, it doesn’t take a lot of effort to account for the errors and improve the results.
Or alternatively, second: Actually, humans need another pair of eyes all the time, including of course in peer review and the scientific process more generally. Not sure when the last time was that you worked with a human, but I can tell you: They make mistakes, too!
This is also why I erred on the side of caution with the “junior researcher” framing (even though junior researchers don’t usually solve major open maths problems right out of the gate).
Third & fourth examples: Working with Claude to make LLMs not fall for fake riddles; also, play Zork!
Finally, we have the two more collaborative (as opposed to, mostly autonomous) runs. These kicked off the whole series. I initially didn’t have a write-up like this in mind, but simply came across some recent papers that I thought would be fun to improve results on with vibe coding. Both papers are of the flavour, “LLMs are bad at X”, and I thought, “maybe not as bad?” (so both of these have LLMs as test subjects as well).
In that regard, these runs are closer to real academic use cases, because they are in response to recent papers, not older classics. And what it all means is that, at least for smaller scale experiments, we are now at a point in time where you can come across a new paper, fire up a coding agent to have a chat, and get some novel results over the course of a weekend (though to be clear, writing these up into proper papers would need a bit more work. I didn’t check the statistical analysis, for example).
These two runs are also representative of a much closer back and forth between the agent and myself, and me generally steering the experiments closely. I won’t be sharing full transcripts for these as they are quite a bit longer and would need a bit more sanitisation to be fit for public consumption. As always, you can however find the researchers’ write-ups and the analysts’ retellings on the landing page.
To me the results are interesting in their own right, so here is a brief summary.
First, this paper by Fascendini et al. shows that LLMs have over-memorised various riddles in the training data, so when you show them an altered version of a riddle that looks similar but actually has a straightforward answer, they tend to respond incorrectly as if it was the actual riddle.
I asked Claude to reimplement the experiments (reusing some of the original published code) and try out some changes. We found that this “riddle prior” is indeed quite sticky, but also that LLM performance increases quite a bit by switching on thinking, and by giving them a prompt that encourages them not to shoot from the hip.
Second, this paper by Gerrits had LLMs play the classic game Zork. They didn’t do so well (though there was no human baseline for comparison), and again the author draws various general conclusions about the capabilities of LLMs.
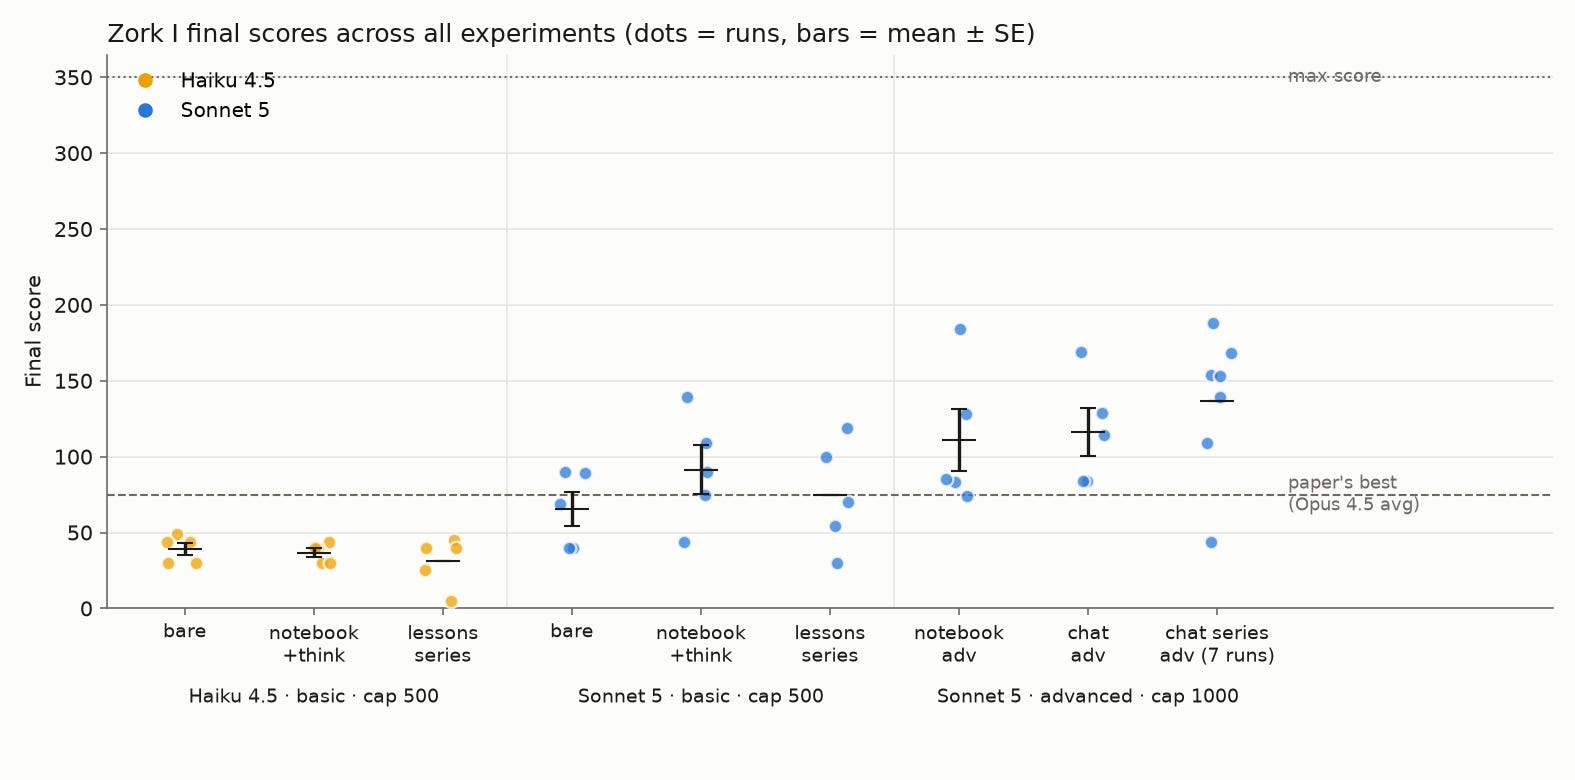
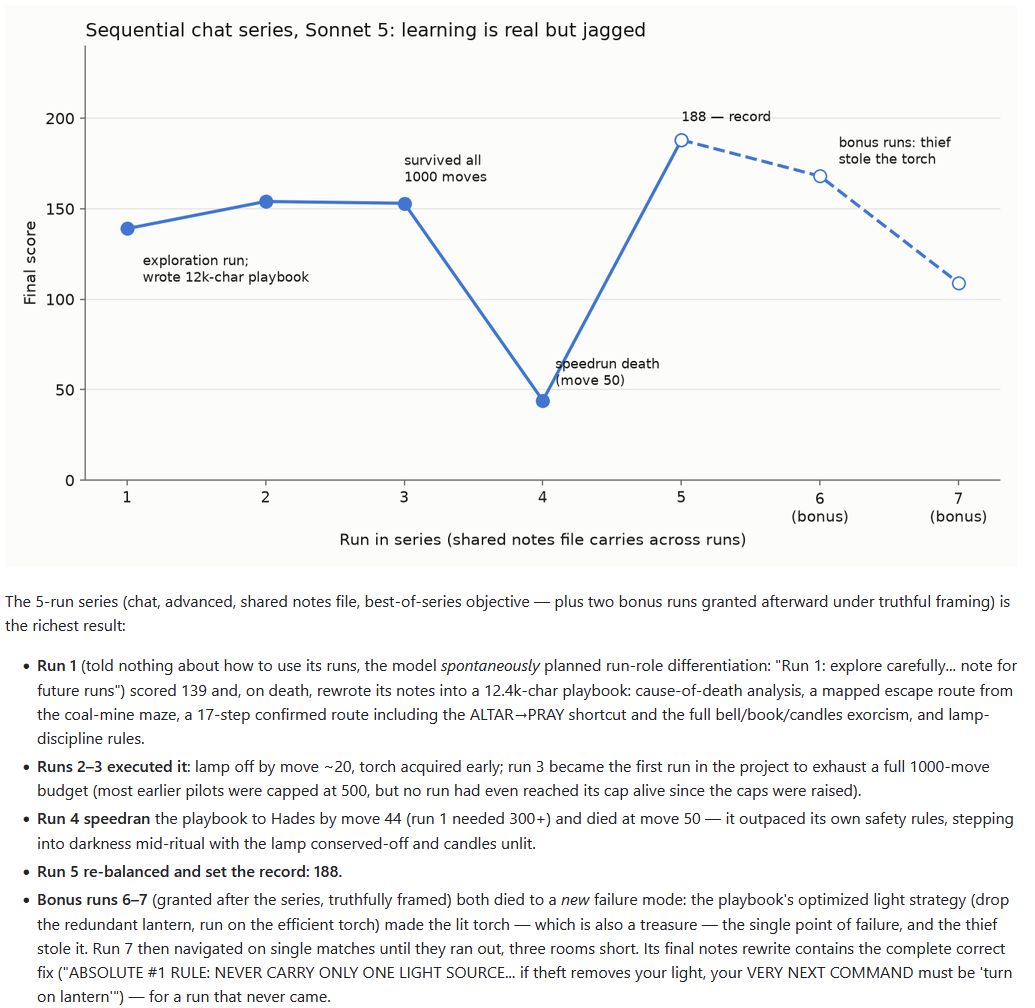
Claude and I improved performance in Zork by a) using more recent models and b) allowing the LLMs to operate more naturally, like verbalising while playing the game. Contrary to the paper, we also found clear evidence of the LLMs learning across multiple sequential attempts at playing Zork.
In a way, the Zork experiment itself mirrors some of the very same lessons that I’ve discussed from the whole project…
Some highlights from the Zork results write-up below.2
The bottom line
So this is where we are at: far beyond the point where all that AI can do is to suggest travel itineraries, with some hallucinated vistas to boot. Instead, we have agents that observe and change their environment, create things, and solve problems.
And this includes scientific work. Next time you come across a paper that looks interesting and doesn’t require too many computational resources (or, well, access to the physical world), why not ask an AI agent to reimplement it for you and try out some ideas.
Yes, AI still has limitations, such as longer-term learning and execution. The experiments I’ve presented each correspond to a few days of human work. AI also still makes mistakes, and sometimes mistakes that humans wouldn’t. The intelligence frontier is jagged. Current AIs might not yet have the same vision capabilities that come so naturally to us, they might not be able to fully control web browsers, let alone robot bodies… heck they might even still miscount how many times a letter occurs in a word (if for good reasons).
Many people will have encountered such problems and quickly generalised that AI just isn’t really that useful. And in the past, that might have been fair. But in the present, there’s a critical mass of things that just plain work, and it takes a more discerning eye to tell what problems are insurmountable obstacles for now, and which can be fixed simply by asking the agent to find a workaround.
And often there are code-shaped workarounds. Going forward, we will find that many more problems are code-shaped than we expected, now that we can summon agents to write custom code on a whim.3
Even if this technology froze in the form it is right now, it is hard to see how it could not have a massive impact on the world. And more and more, and for good or bad, that impact will come from actions taken by independently acting agents, and not from some tool tightly controlled by its human wielder.
At this point, I find it hard to grasp why some still argue that these systems shouldn’t be called “artificial intelligence”. Similarly, Alison Gopnik of AI-as-cultural-technology fame was asked what would change her mind about AI, and responded:
If you had a system that could go out and explore the actual external world autonomously itself and change what it thought based on its exploration…that would be more like the kind of autonomous intelligence that a two-year-old has.
I think qualitatively we are already there, and the rest might come quicker than you think. Because you know what can be used as an interface to the external world? Code.
Lastly: a note on anthropomorphising language
At the beginning I promised a comment on anthropomorphising language. In some cases, that’s just the jargon of the field, like “thinking steps” in the maze experiments, or attention or chain-of-thought in LLMs. But I also characterised my own interactions with the agents as the agents having ideas, making decisions, learning lessons from mistakes, and so on… basically describing them as I would humans or other biological agents like animals.
On some level, this also irks me a bit. I’m not a professional philosopher, but I do have a nitpicky streak that makes me want to caveat everything, and channel my inner David Chalmers by prefixing a precautionary “quasi-” every time I use one of these terms. And I say this even though I’m actually sympathetic to arguments that would justify the application of cognitive terms to these systems even on a more fundamental level.
But here is the thing. The more AI acts like agents, the harder it will be to avoid such language, especially in our everyday interactions with them. And at this stage, questions of “true phenomenal consciousness etc.” aside, I do think such language is useful in conceptualising how agents behave (also see the Chalmers paper I just linked).
There are pitfalls to this, and sometimes such intuitions will fail and mislead us. The solution here is to apply caution and educate the public around this, not to be overly prescriptive in how we use language. Just because artificial lawns are not as good as the real deal doesn’t mean they can’t be called artificial lawns.
And if a truck can struggle up a hill and a river can find its way to the sea, then Claude can reason its way through a machine learning problem.
Acknowledgements & notes
Thanks to Adam Santoro for earlier discussions, Karen Jeffrey and Davide Vercelli for feedback.
The tool to make nice-looking conversation transcripts is a custom version of claude-code-transcripts by Simon Willison. Underlying research papers, and reused code (answer-judging in the “riddle riddle” run), are cited in the respective write-ups.
This post was written by me, taking into account minor grammar and clarity feedback from AI.
Citation helper:
Reichert, D. P. (2026). ‘If you haven’t recently used Claude Code*, you might not understand where AI is at’, David P. Reichert’s Substack, 03 August. Available at: https://davidpreichert.substack.com/p/if-you-havent-recently-used-claude
(Accessed: <your date>)
E.g., questions of phenomenal consciousness or moral status.
Nicely conveyed in Hank Green’s recent video on the Jevons paradox.
I think the point is that frontier LLMs are impressively useful now but to leverage their best skills you need to let them write and execute code to do it. For many people - maybe most people - that's an alien and slightly scary concept because they just aren't familiar with programming. As the LLM become more able to do that sort of thing in the background I suspect more general uptake will increase.
Mathematician here. I was part of the crowd a year ago that said AI couldn't reason. The newer models absolutely do have reasoning capability, and anyone who has to qualify that with "quasi-" is demonstrating that they don't really understand what reasoning is themselves.